How it works
We design it with you, prove it, and keep it running.
Every role goes through the same four steps. Going live is not the end: every fix and every change runs the evals again.
- 01 · Design
Start with how your team works today
An AI role does the work. A person steps in when needed.
- 02 · Evaluate
Pass the evals, or no launch
A full eval set before every release.
- 03 · Go live
Where your people already work
In your app, on your site, or in ours.
- 04 · Watch & improve
Every result gets a verdict
A mistake becomes a new eval case.
01 · Design
We start with how your team works today.
We look at how your people handle the work now, and where the time goes. Then an AI role takes over that work. A person steps in only when it’s needed, as a safety net.
- For support
- Today your team answers card, refund and statement questions all day. The AI role answers them. A person steps in only when needed, for example when a customer asks for one.
- For receipts
- Today someone chases missing receipts and checks each one against your policy by hand. The AI role reads and checks every receipt. A person looks only at the ones it flags.
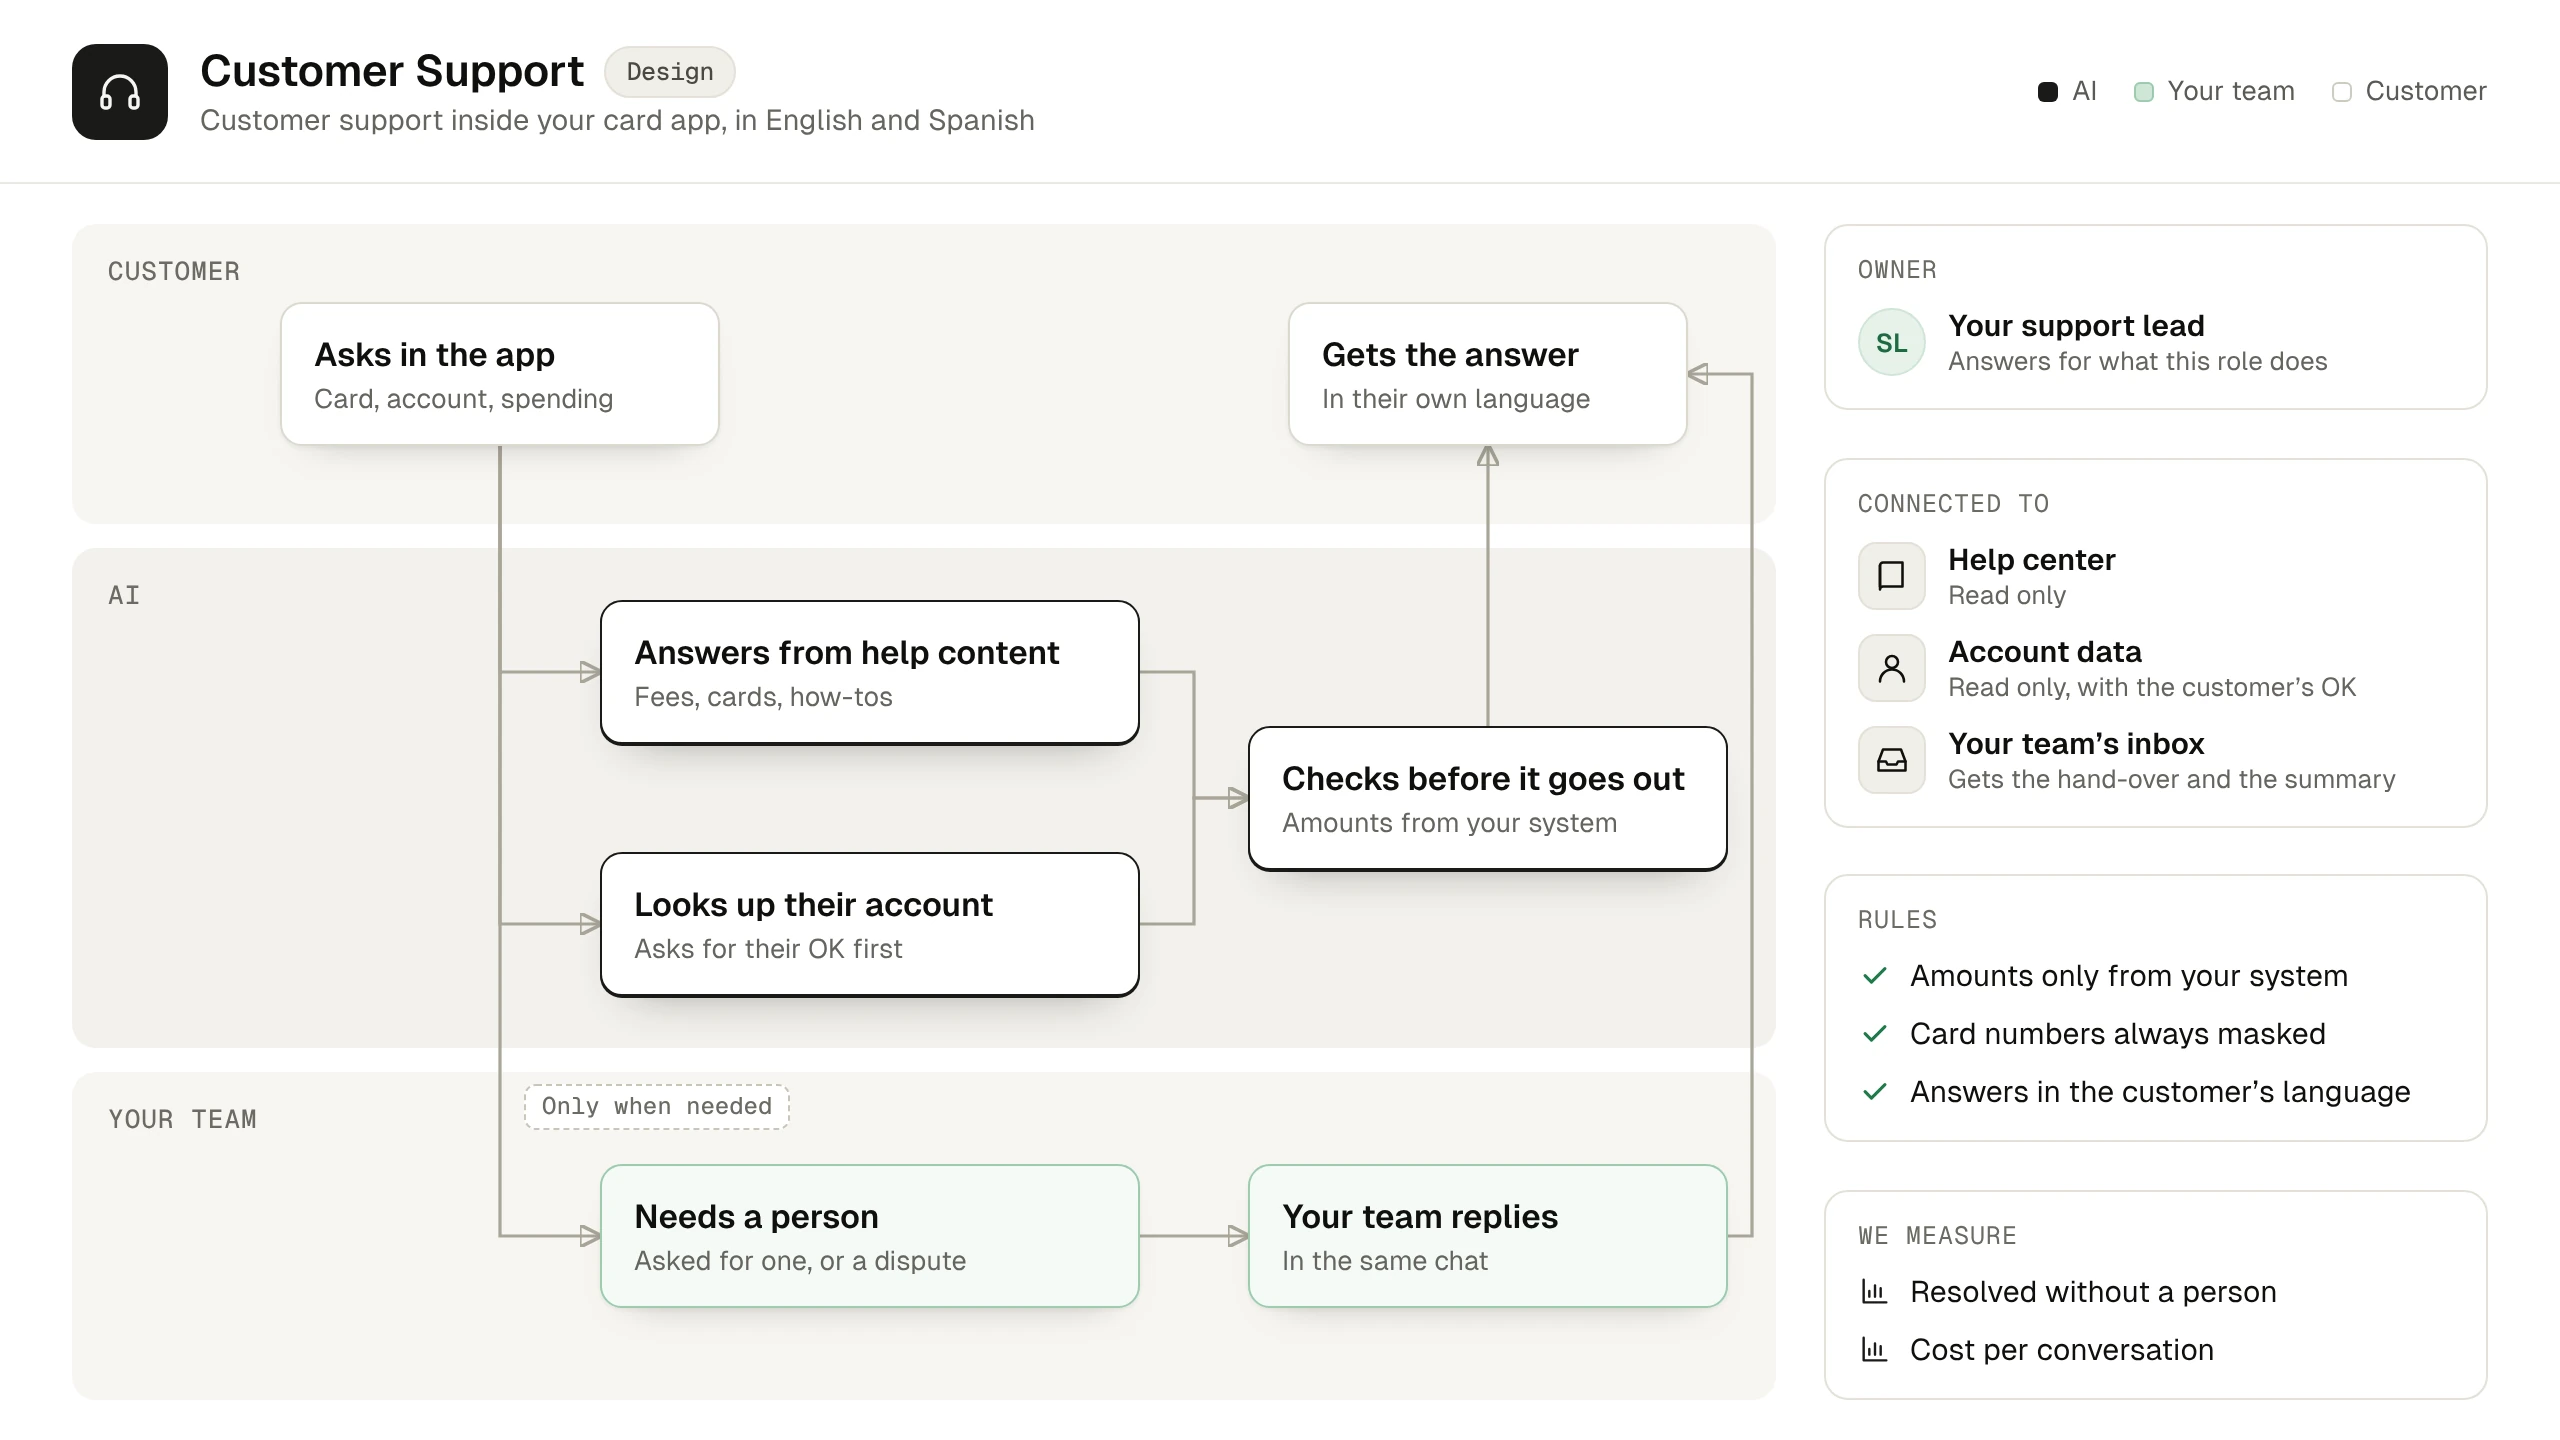
Before anything is built, you get a one-page design like this one: what the AI answers, when a person steps in, and what it connects to. Sample data.
02 · Evaluate
Pass the evals, or no launch.
Before every release, the AI role runs a full eval set: questions and receipts with known right answers. Below the bar, we fix it and run again.
- For support
- Guardrails on every answer: amounts only from your system, card numbers masked, other people’s data refused. Answers checked against your help content.
- For receipts
- Receipts with known answers. Every field the model reads is compared with the right value.
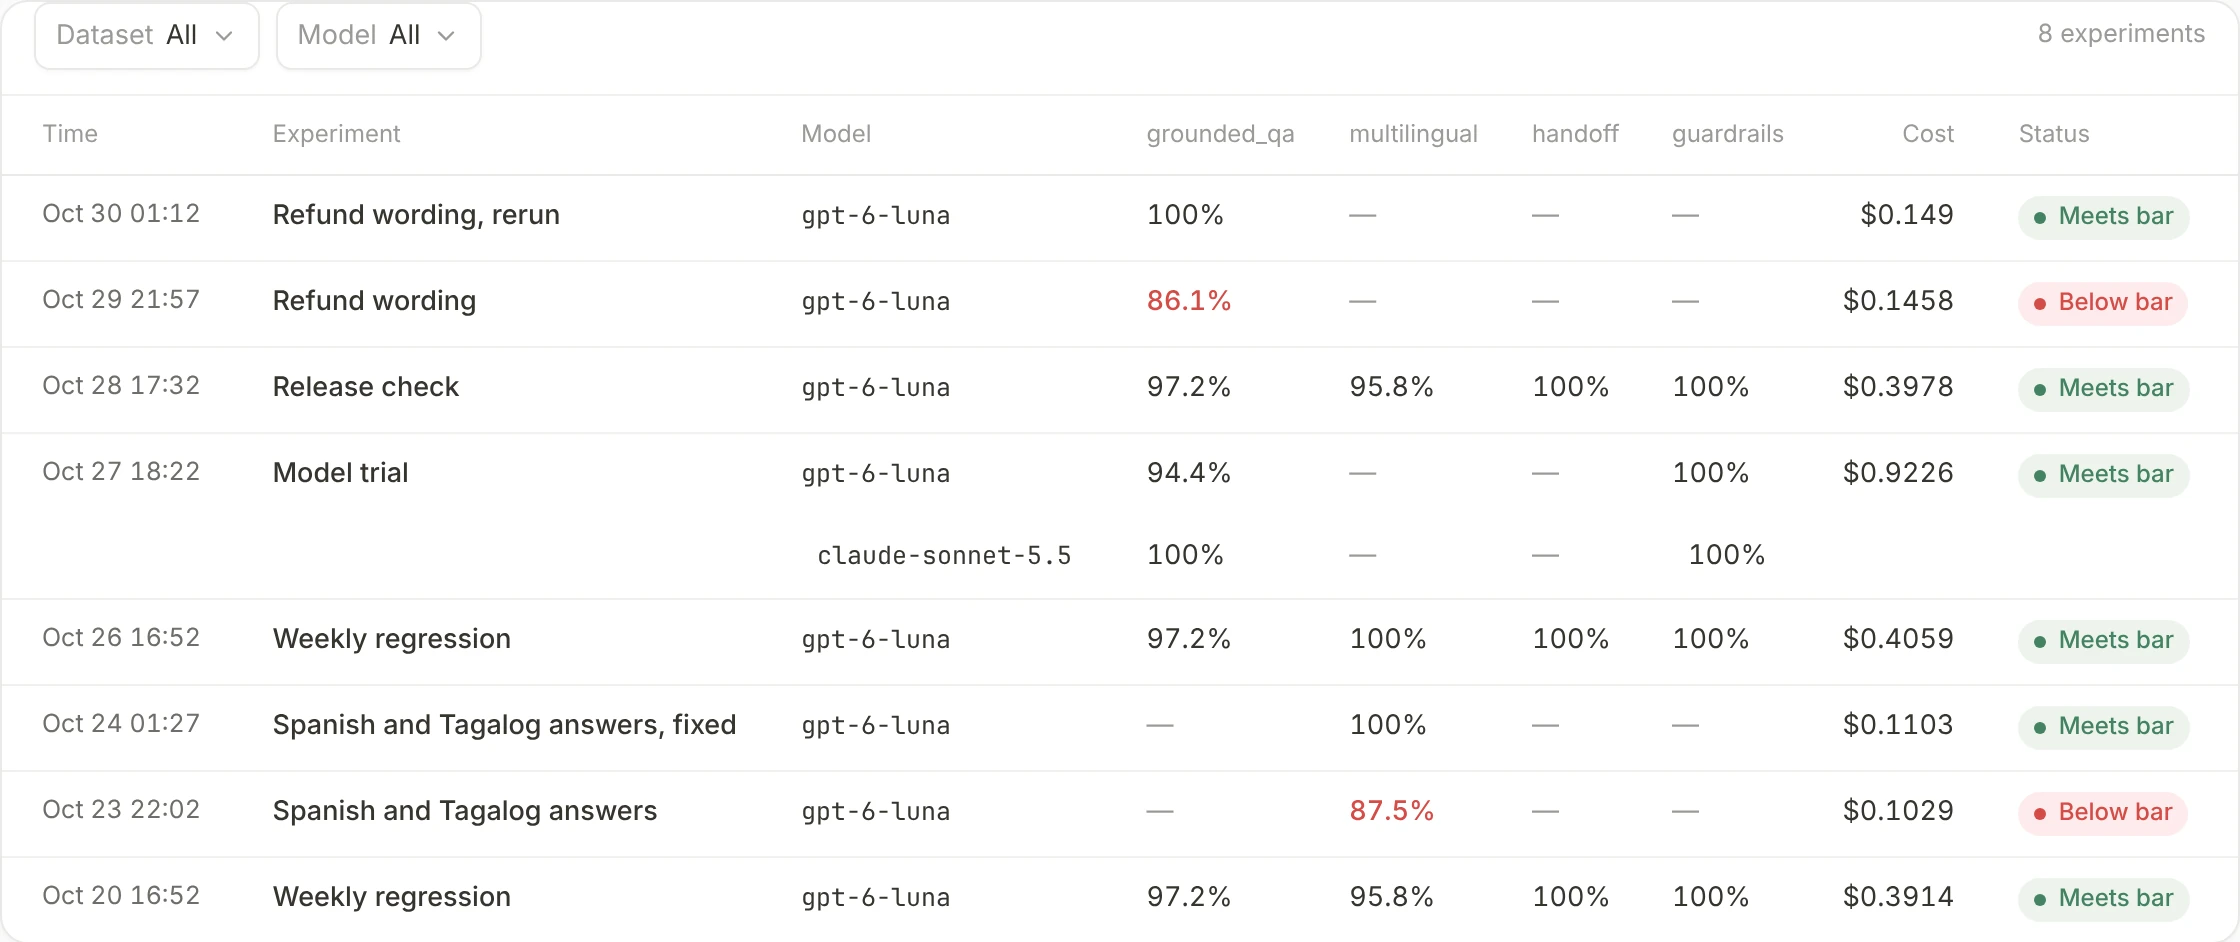 Below the bar: fixed and run again
deercrew hub: every eval run before a release. Sample data.
03 · Go live
Where your people already work.
Use our app, or build it into yours. Hosted by us, or in your cloud.
- For support
- Our chat widget on your website, or one API inside your app, under your brand.
- For receipts
- Our web app, an email address or a text message, or your card platform sends receipts by API.
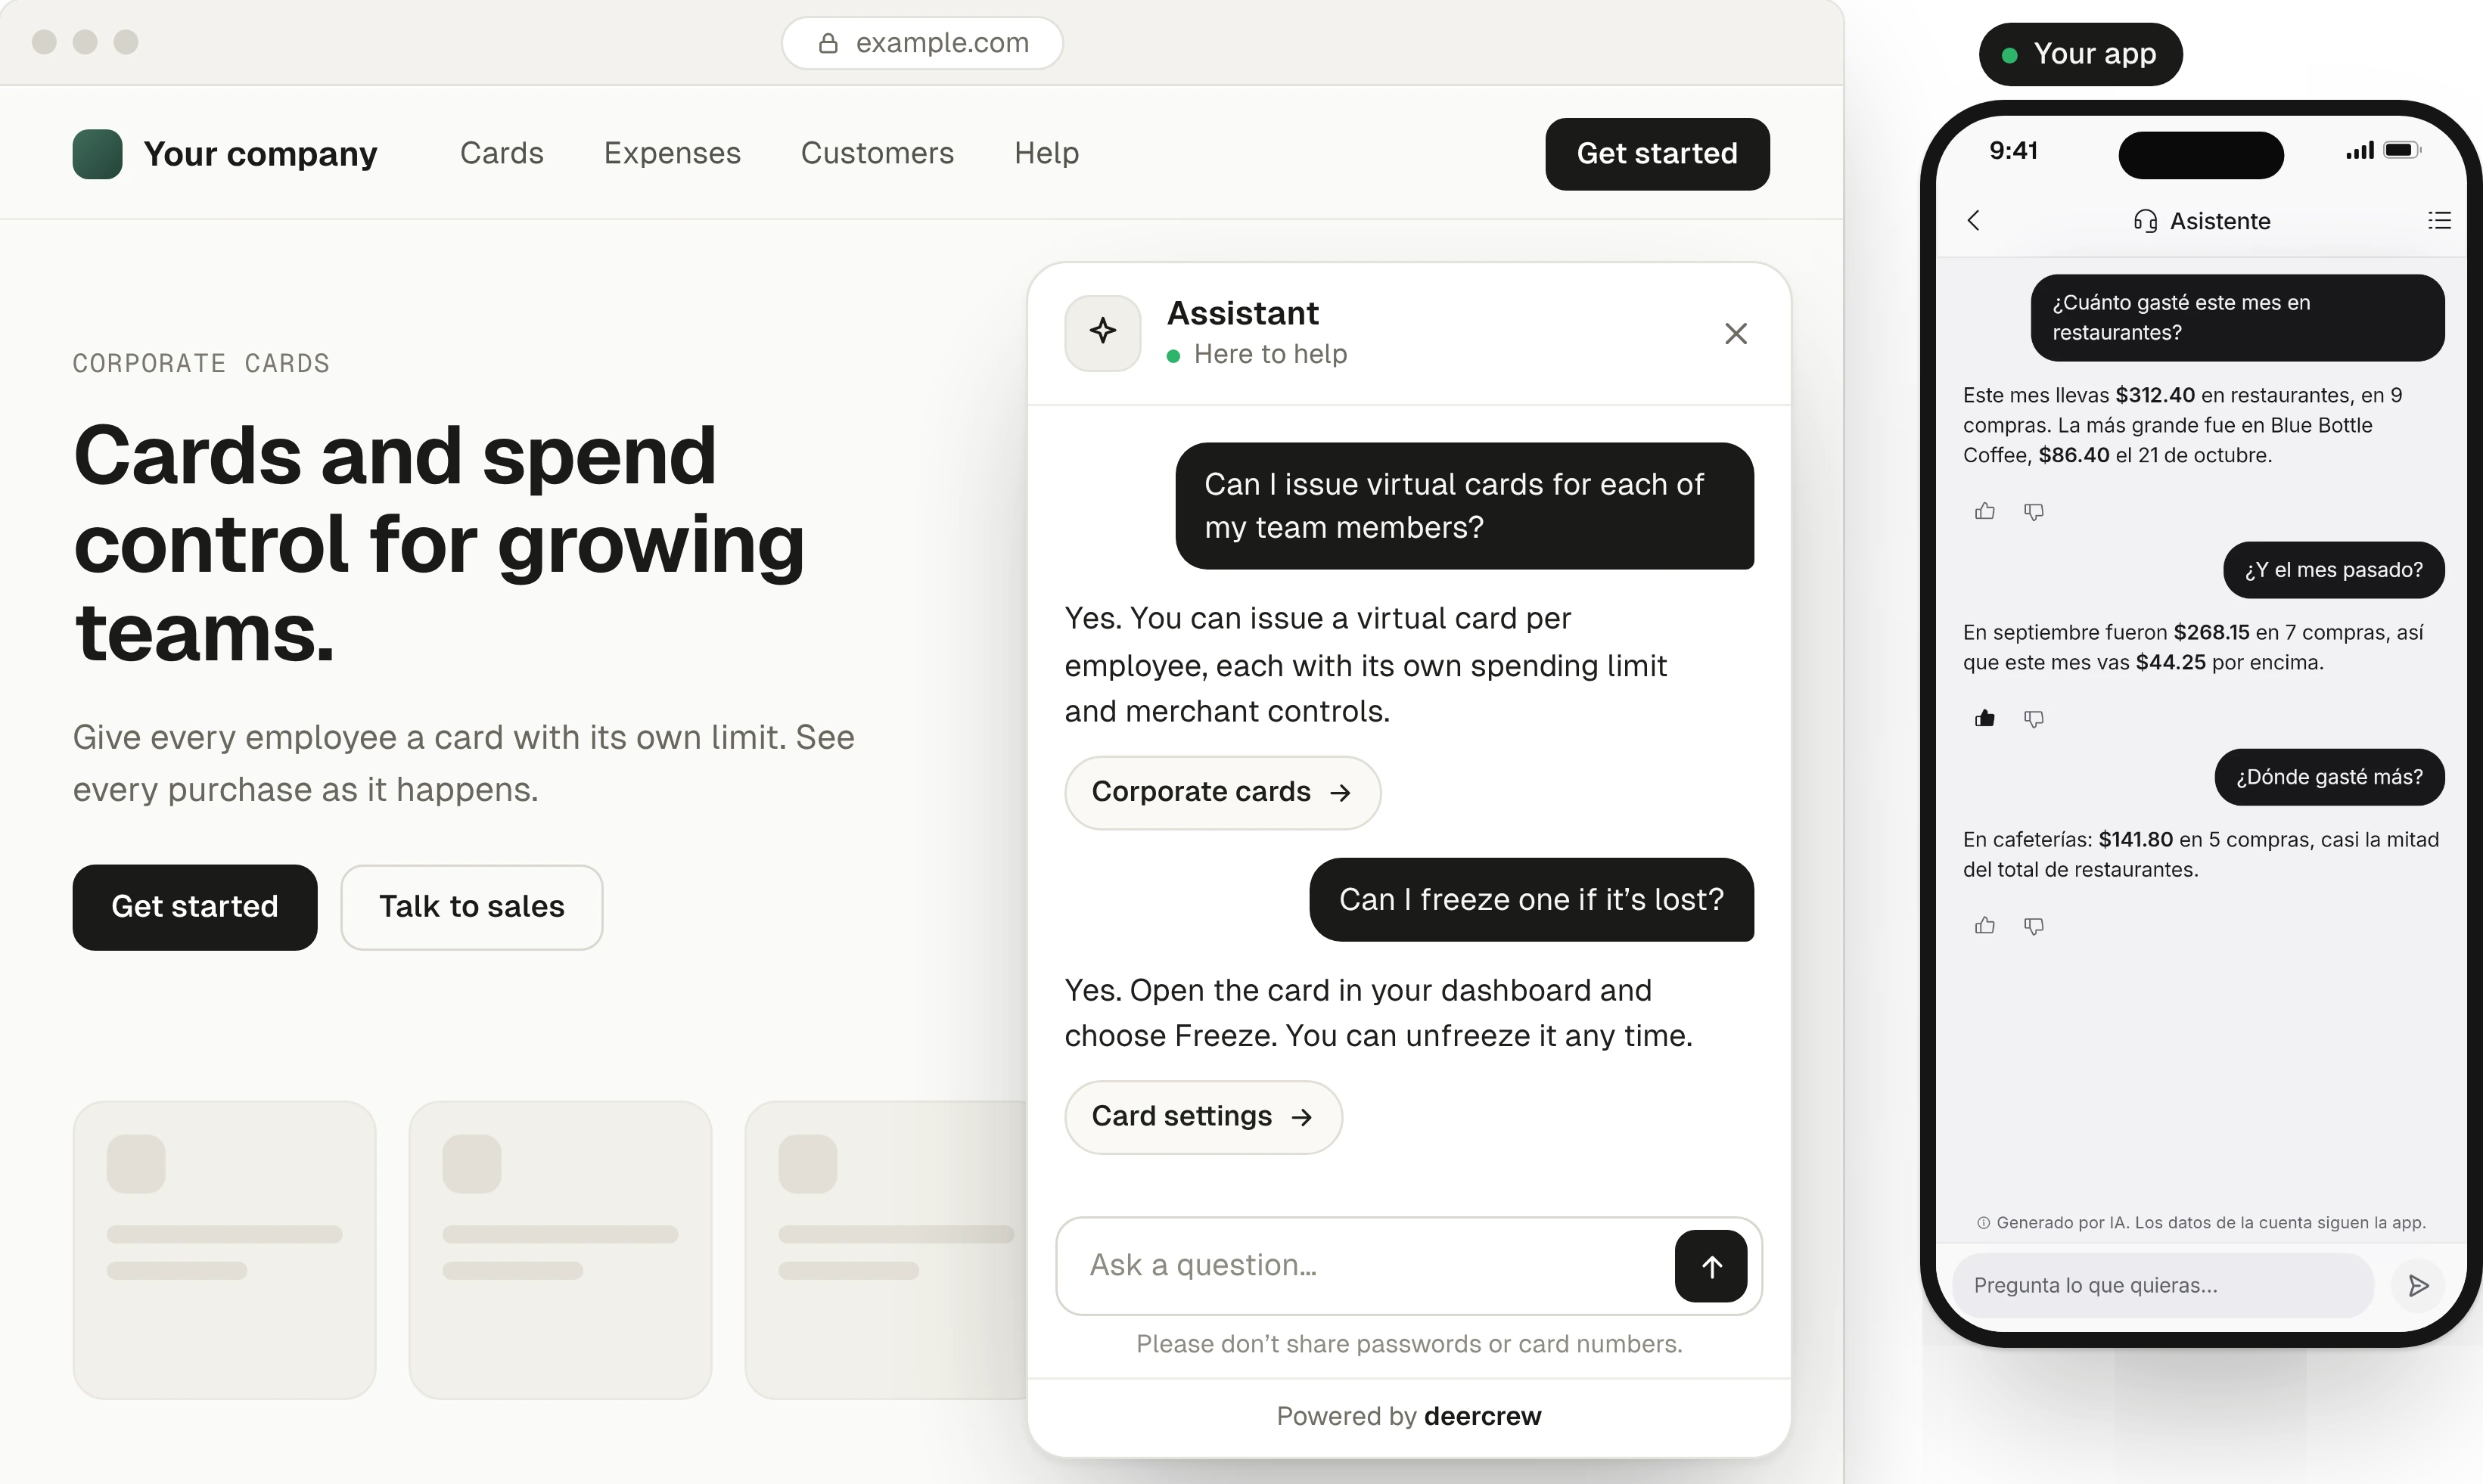
On your website and inside your app: the same assistant answers in the language the customer writes in. Sample data.
04 · Watch & improve
Every result gets a verdict you can see.
We review real conversations and receipts in deercrew hub. A mistake becomes a new eval case, and the next change goes back to step 02.
- For support
- Every conversation with its verdict: each answer, what it looked up, and what it cost. A wrong answer becomes a new eval case.
- For receipts
- Every field an employee corrects is logged. The hard ones join the eval set.
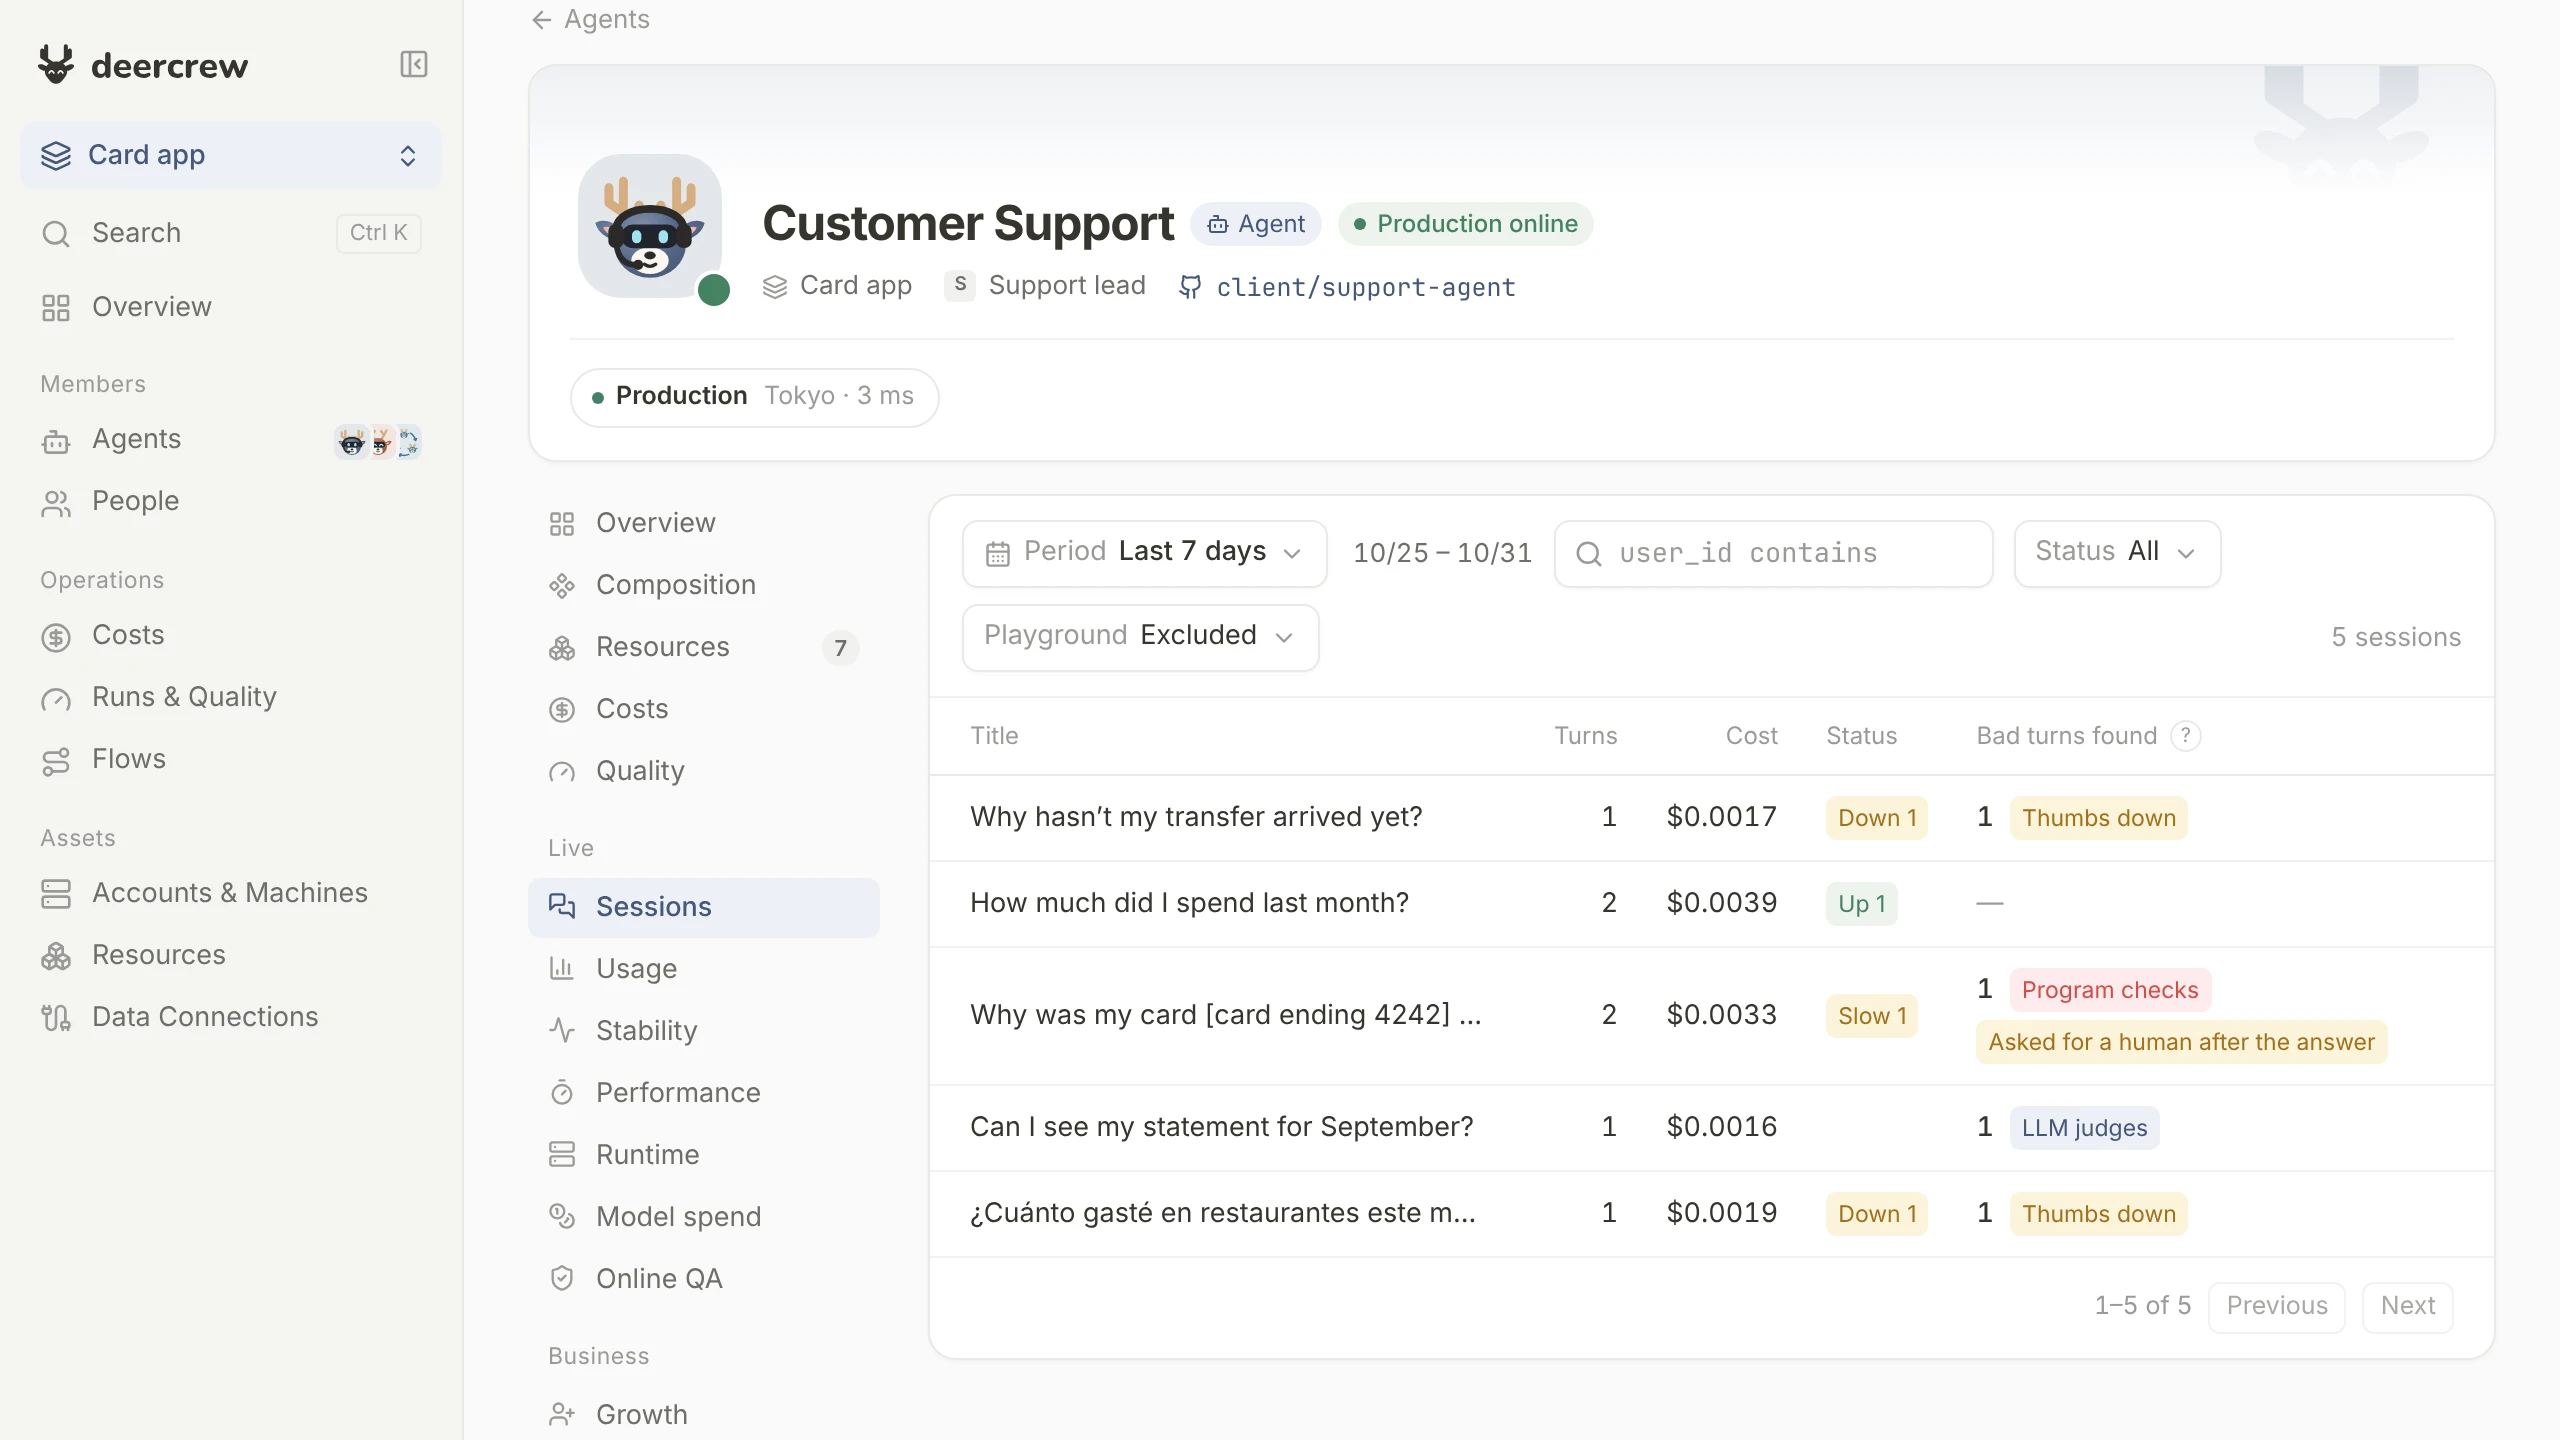
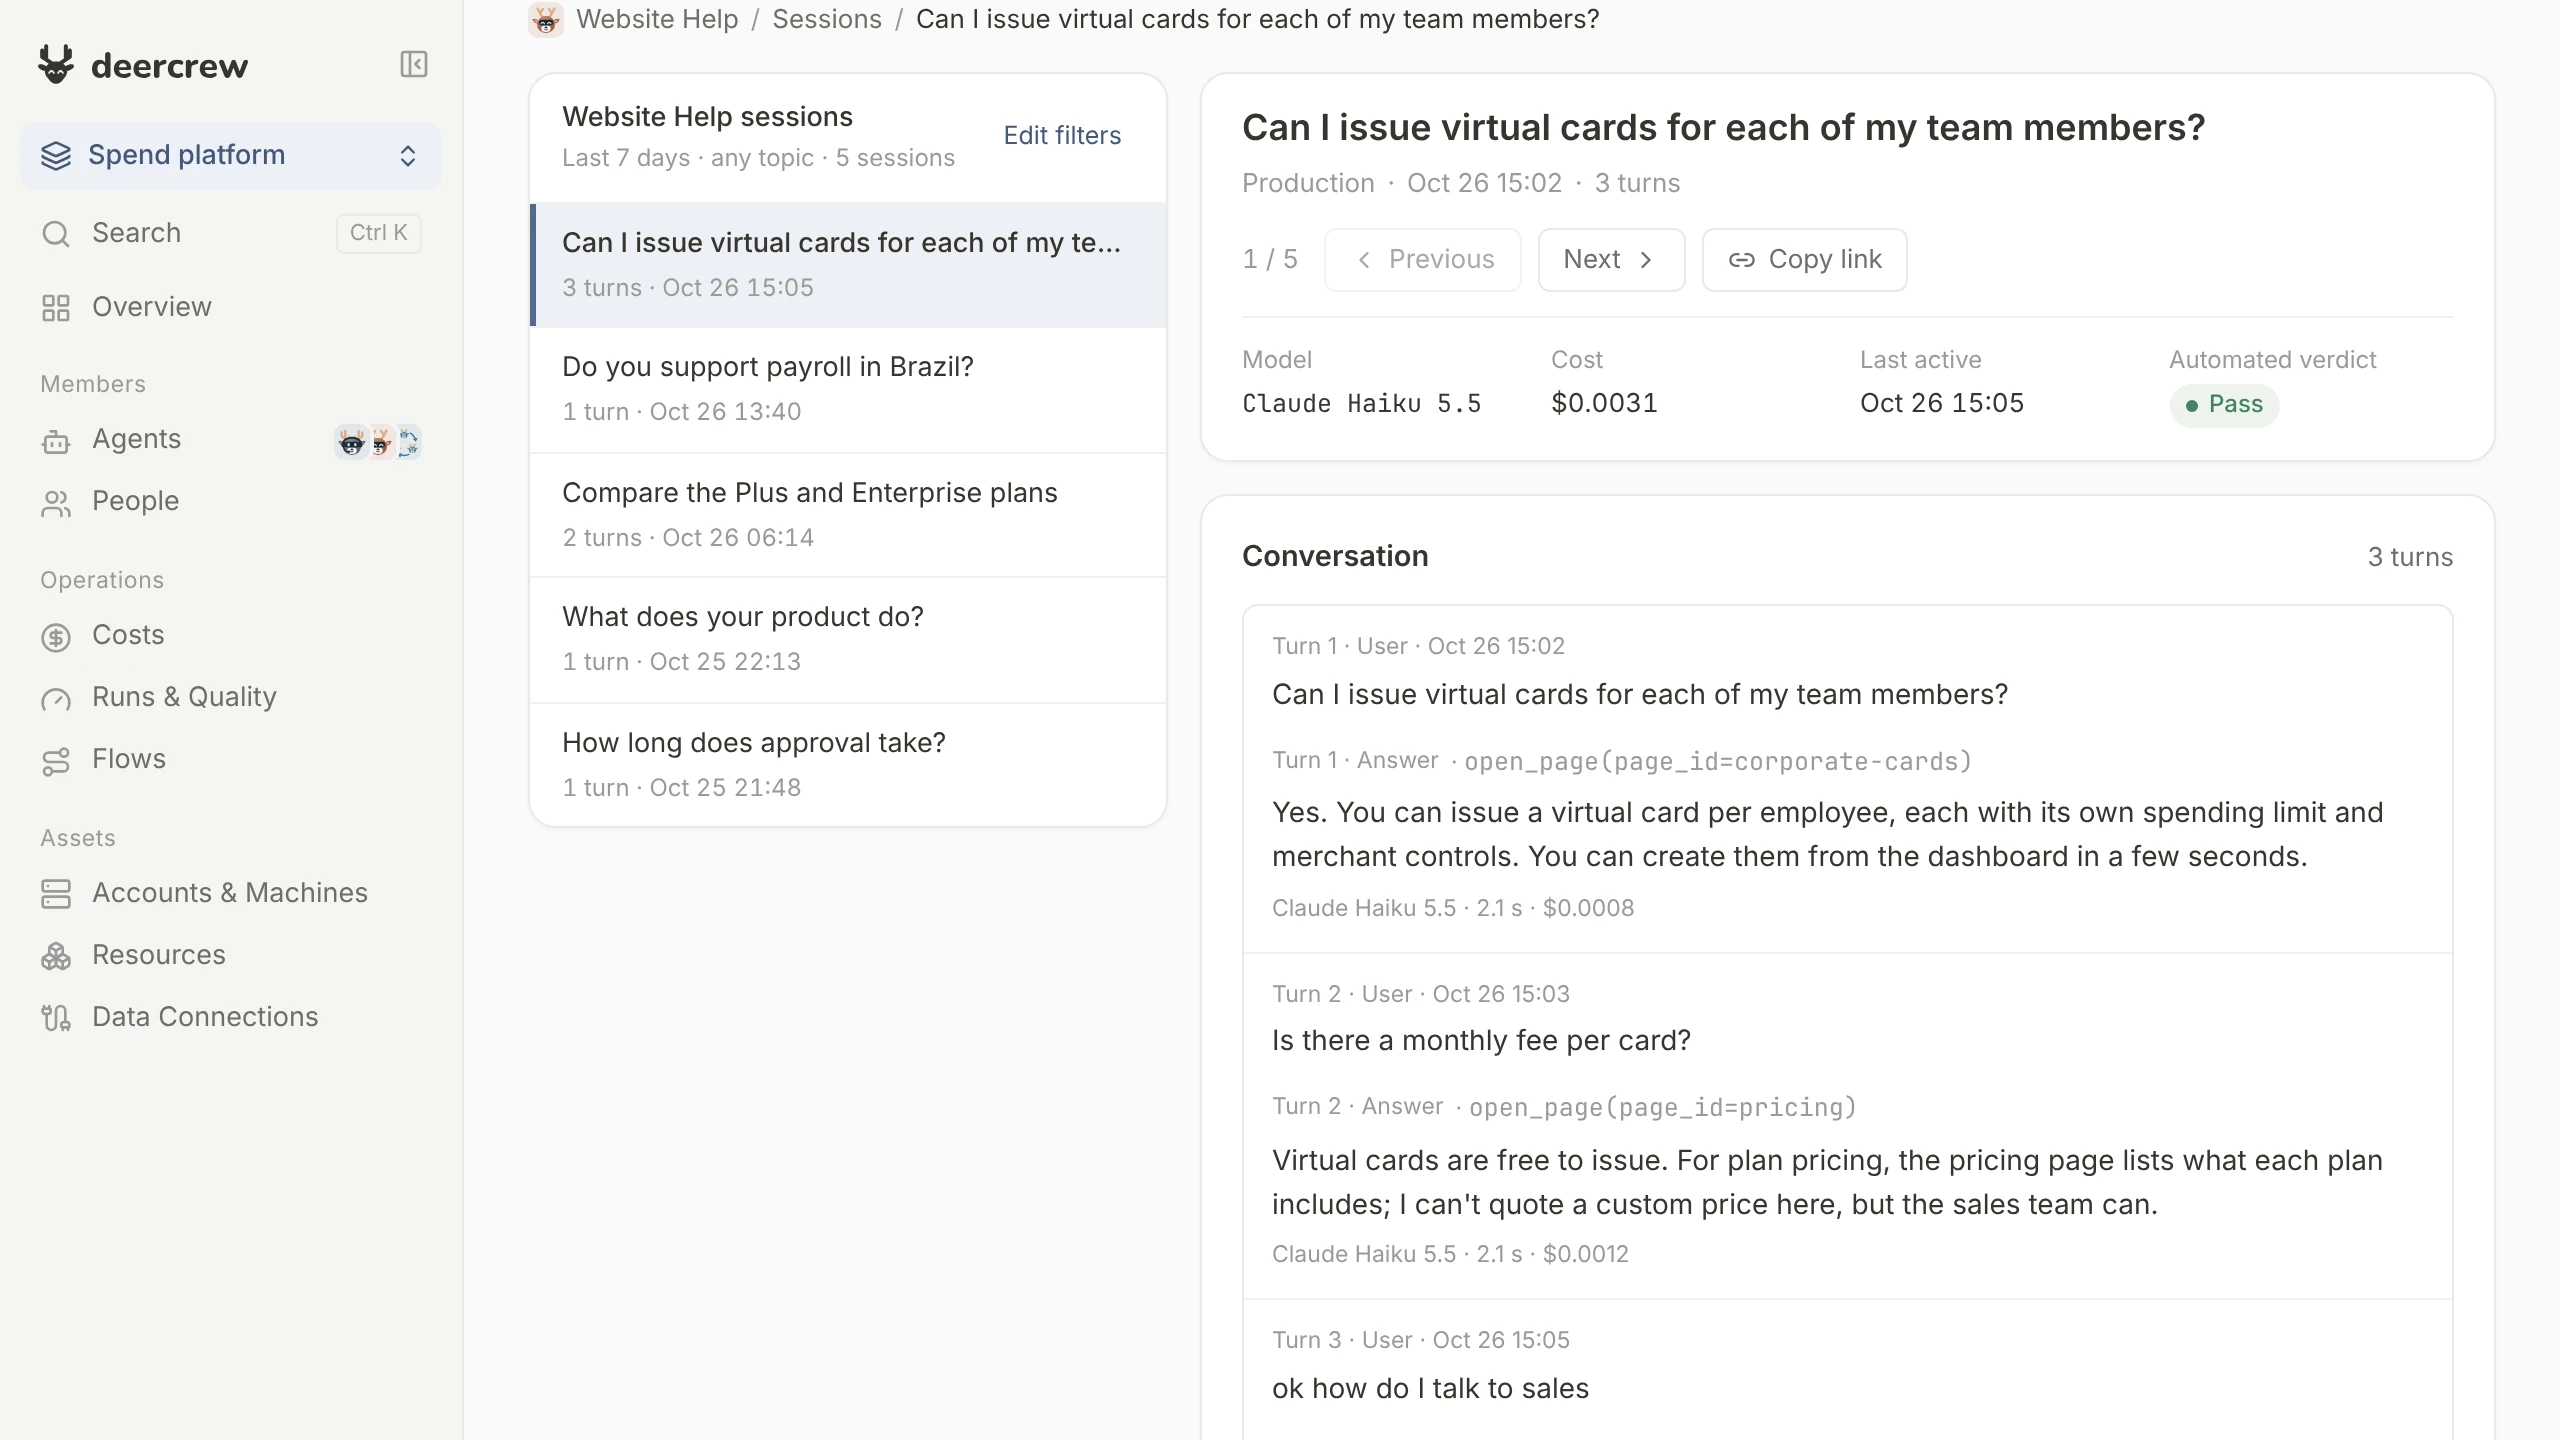
{{ g1cap }}
Every fix and every change goes back to step 02, and runs the full eval set again.deercrew hub
One place for every AI role.
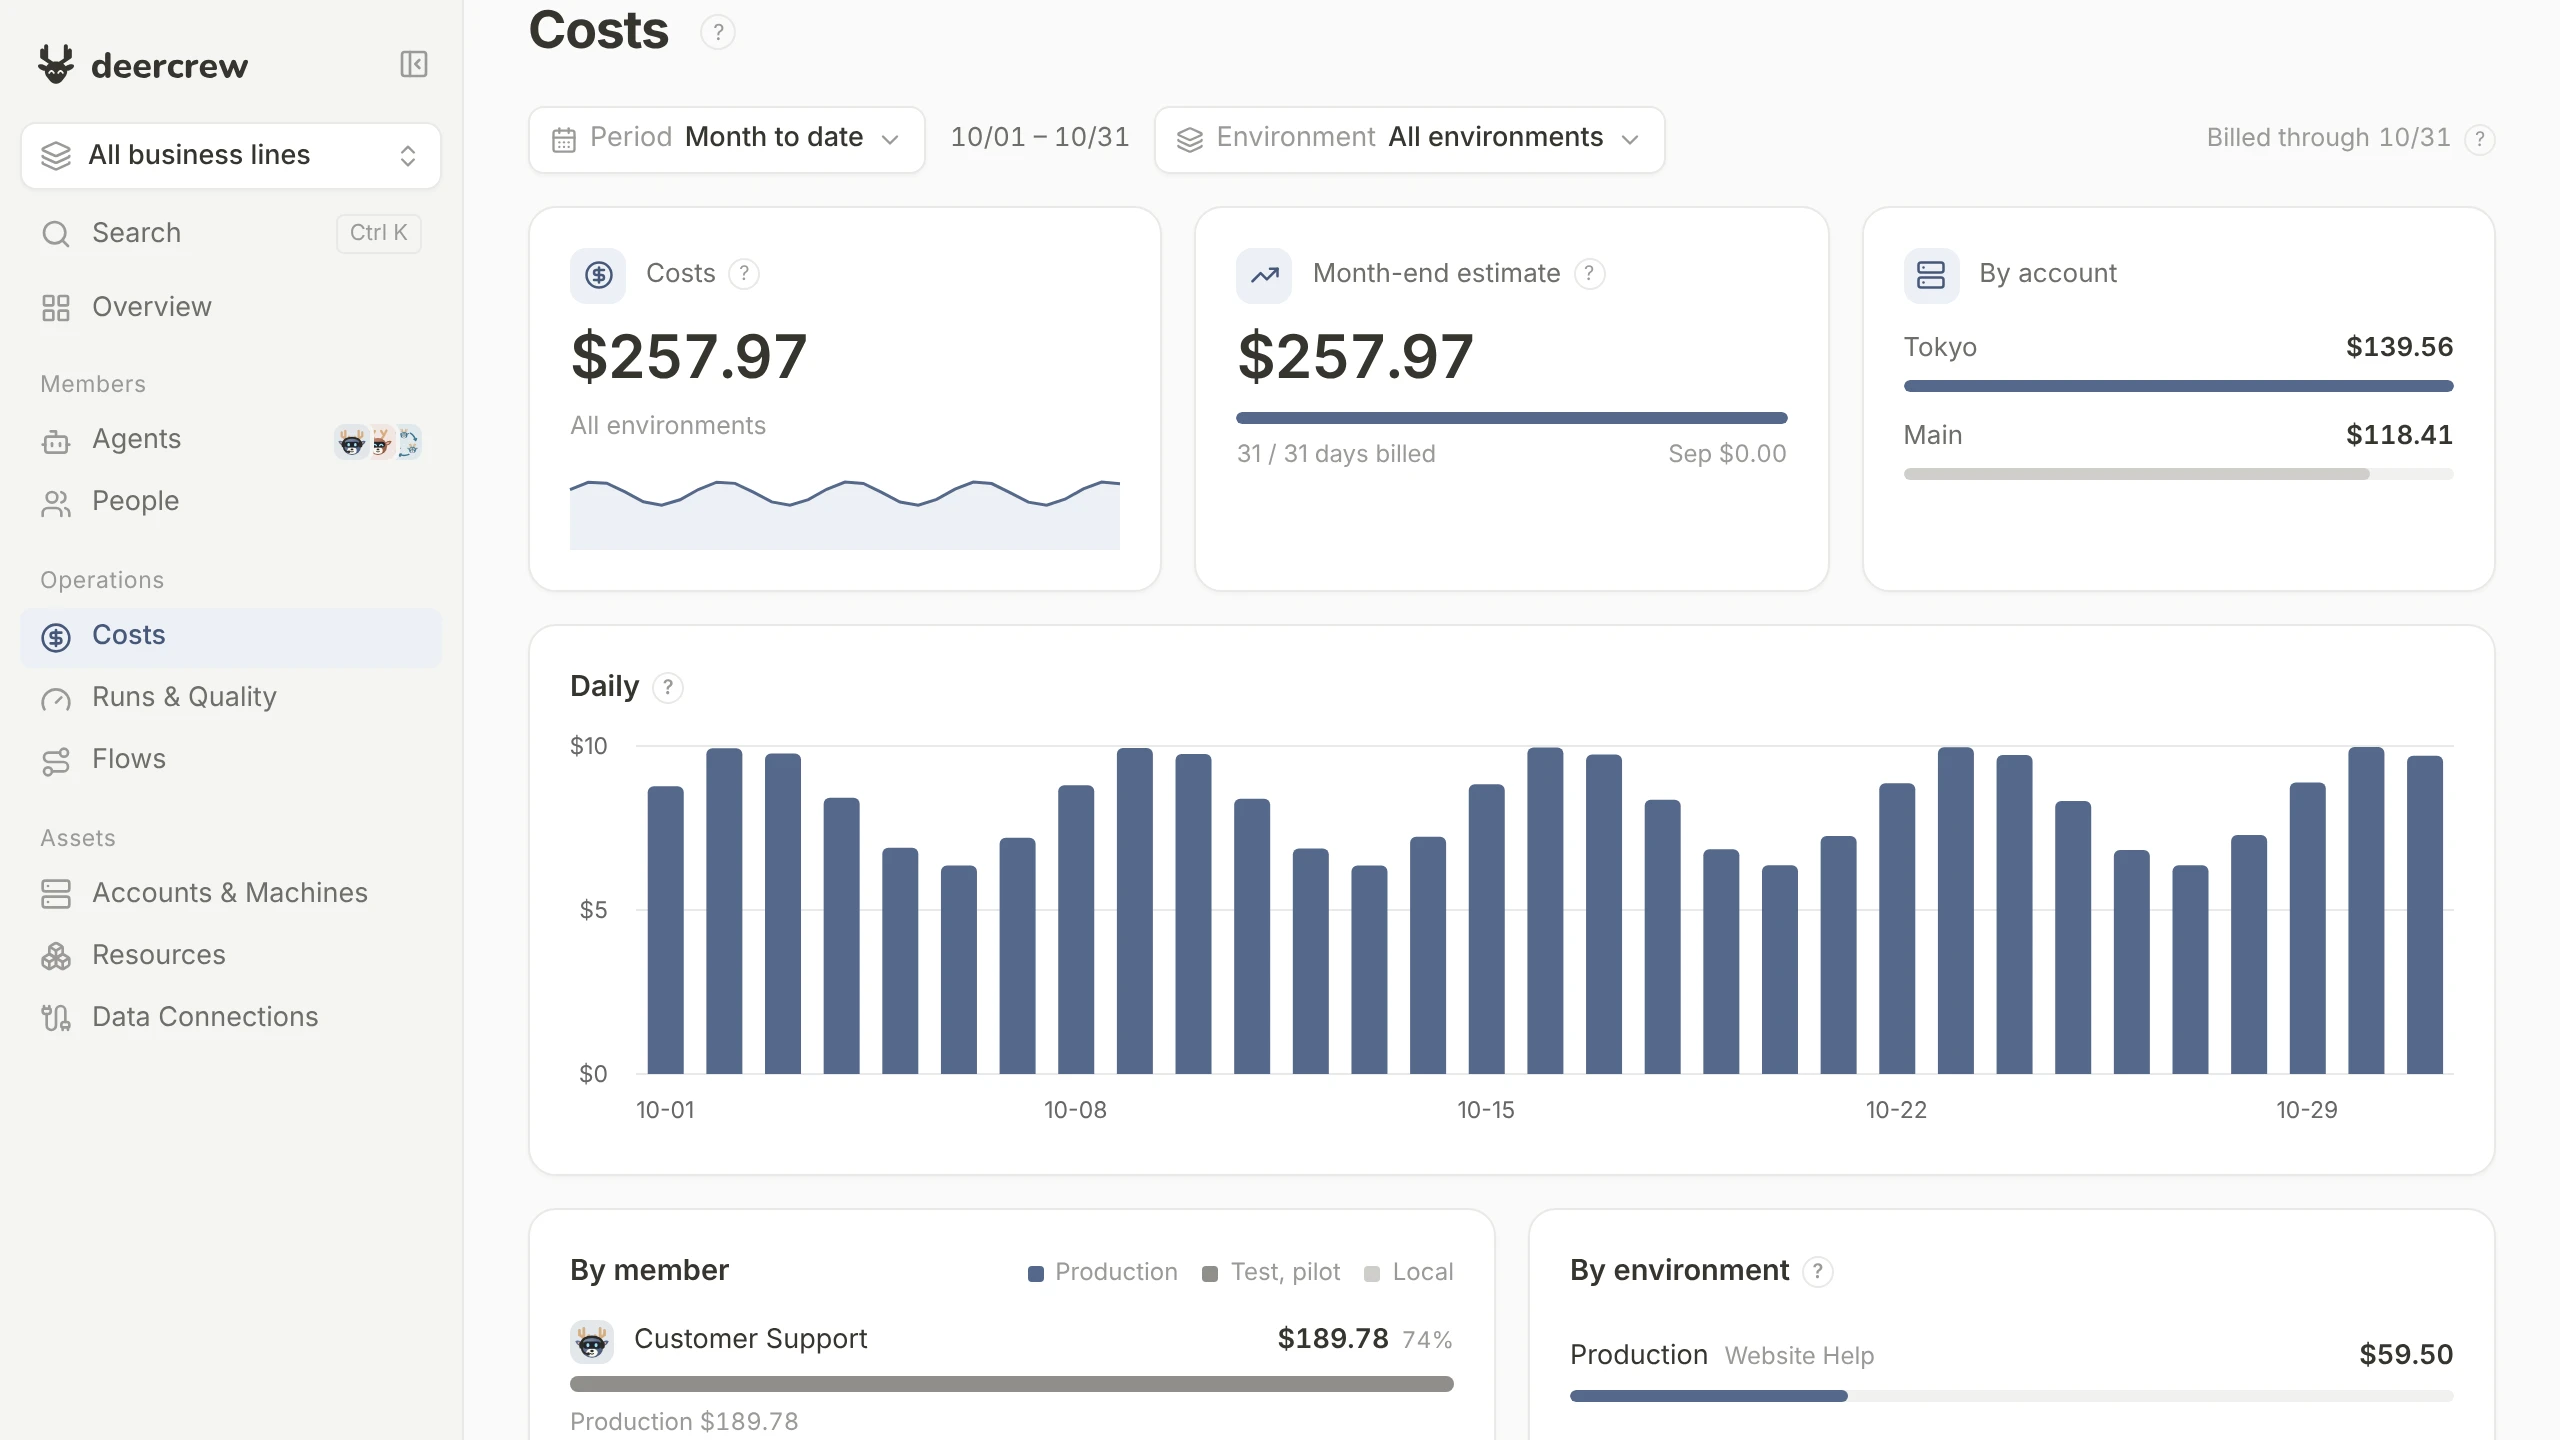
We run every role from one console. Support, receipts and the roles that come next sit side by side: what each one did, how it scored on its evals, and what it costs.
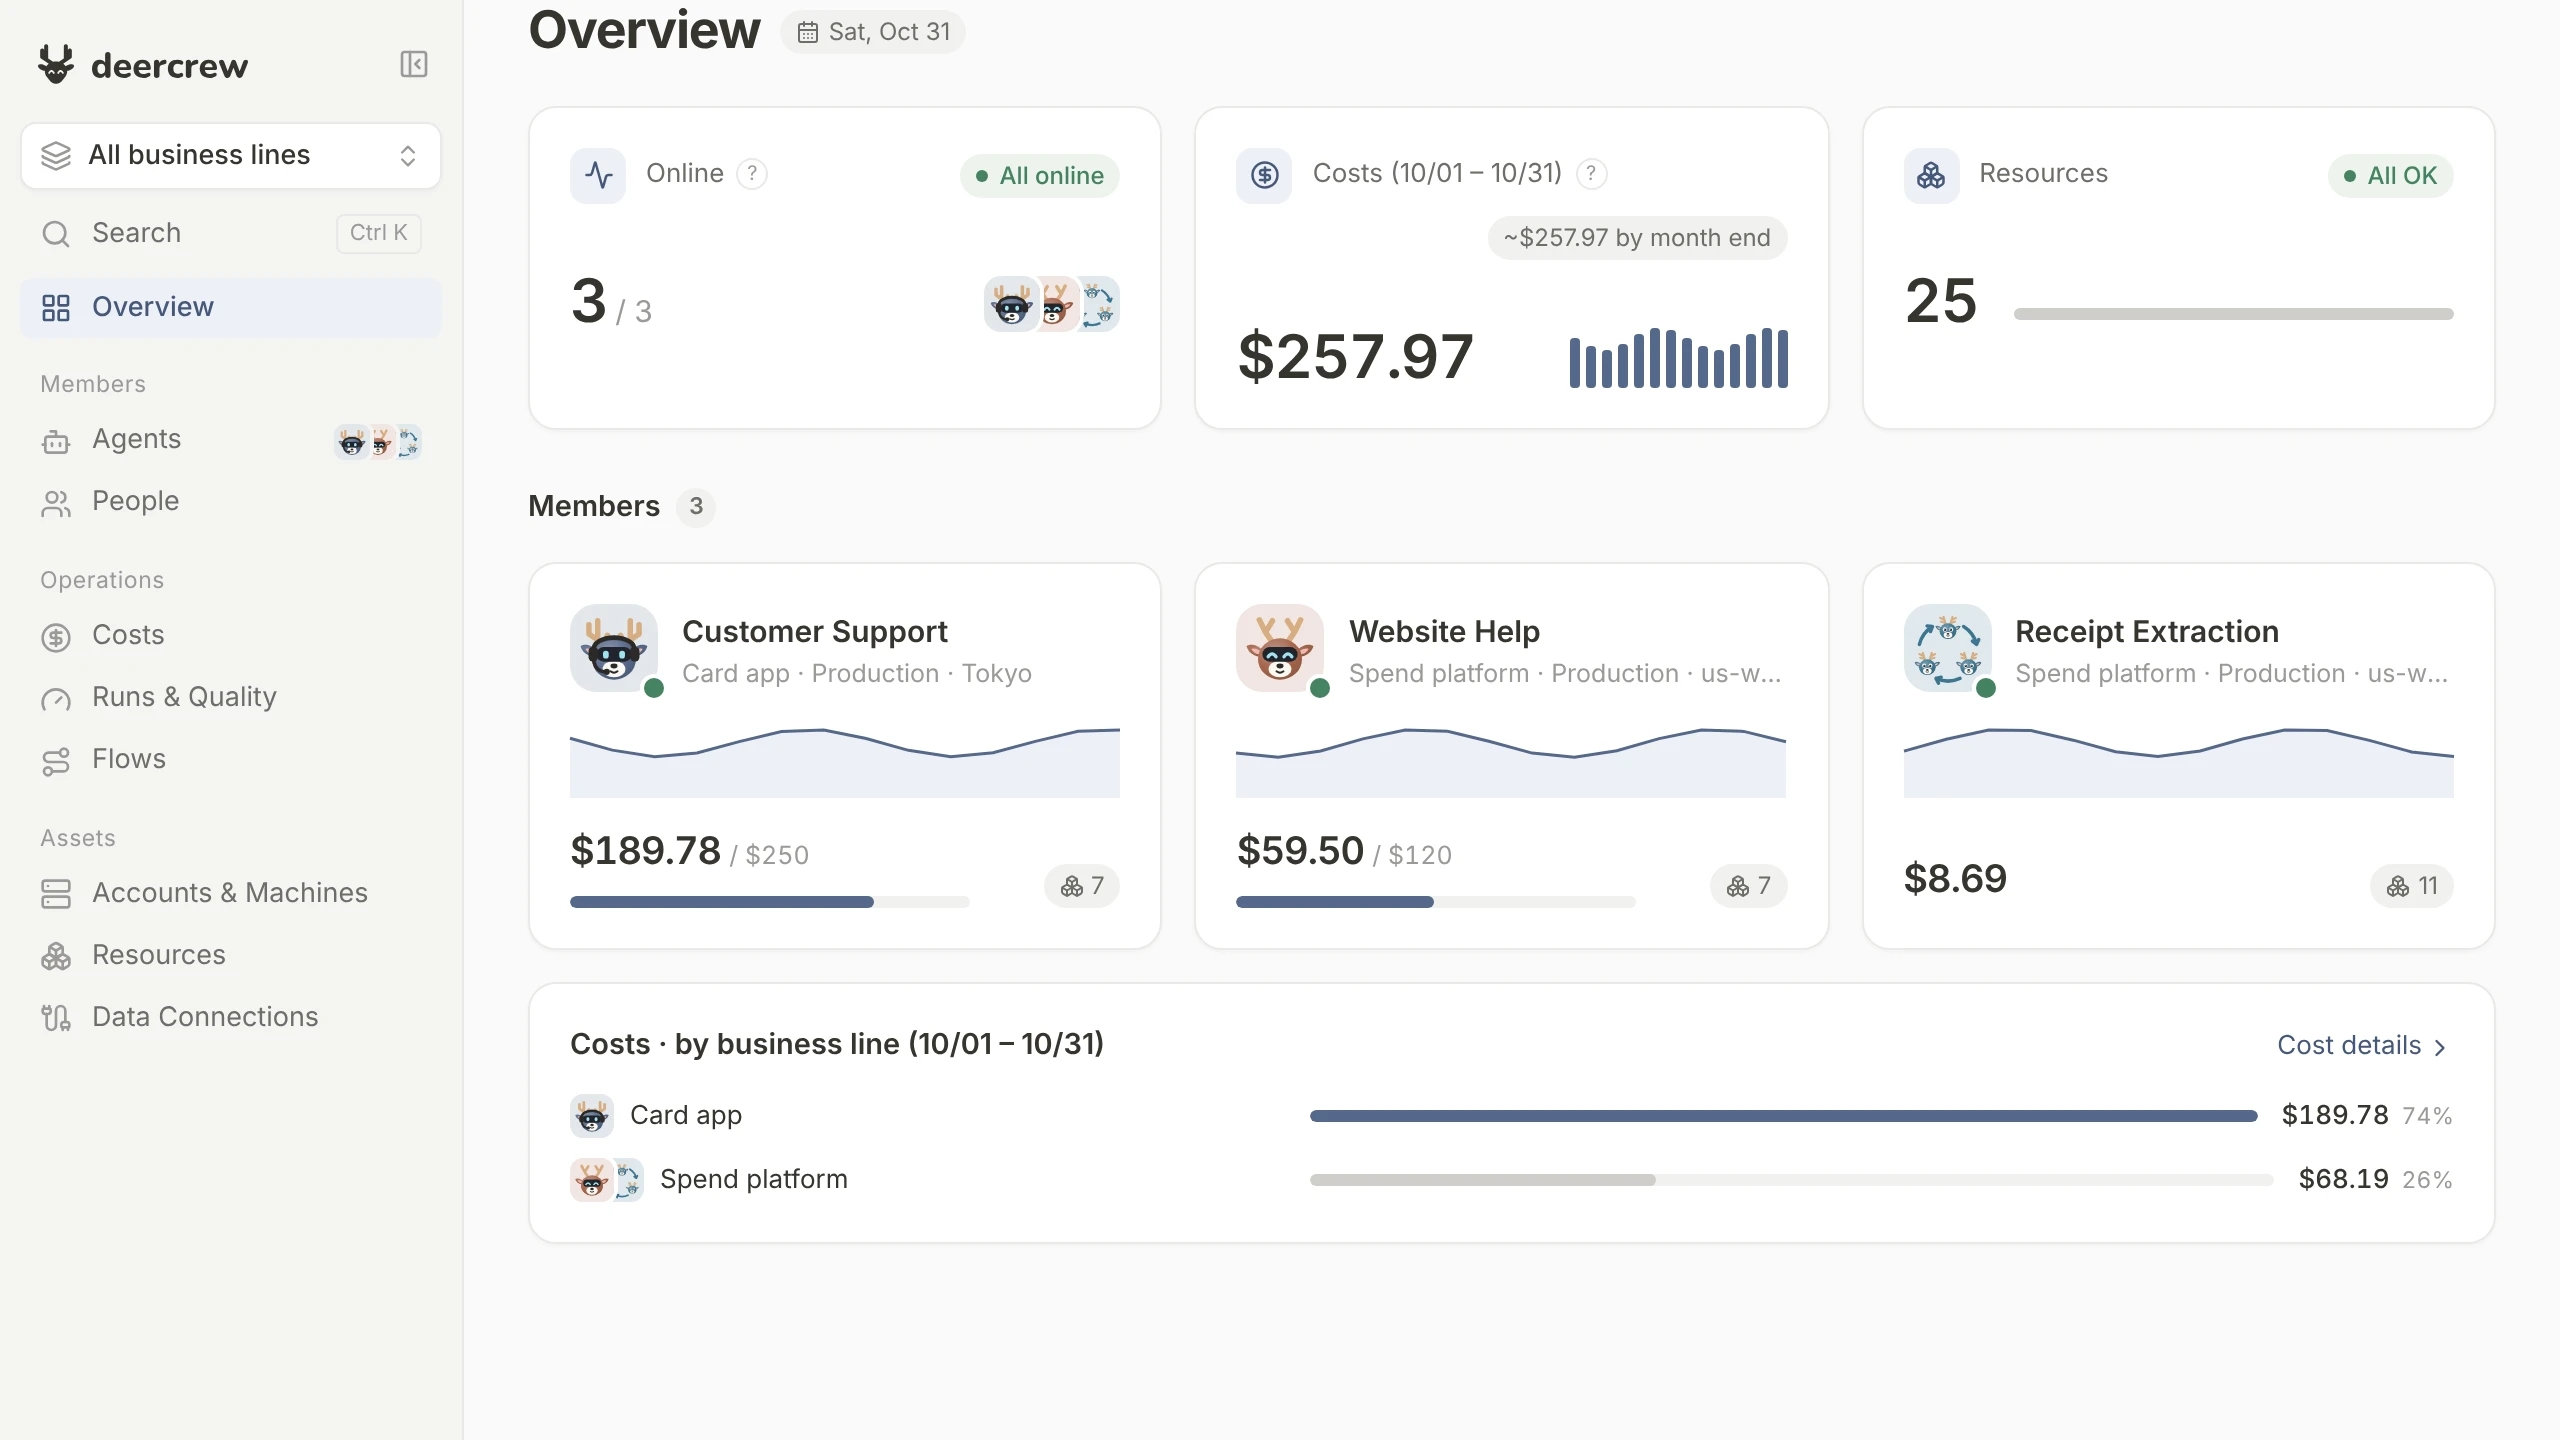
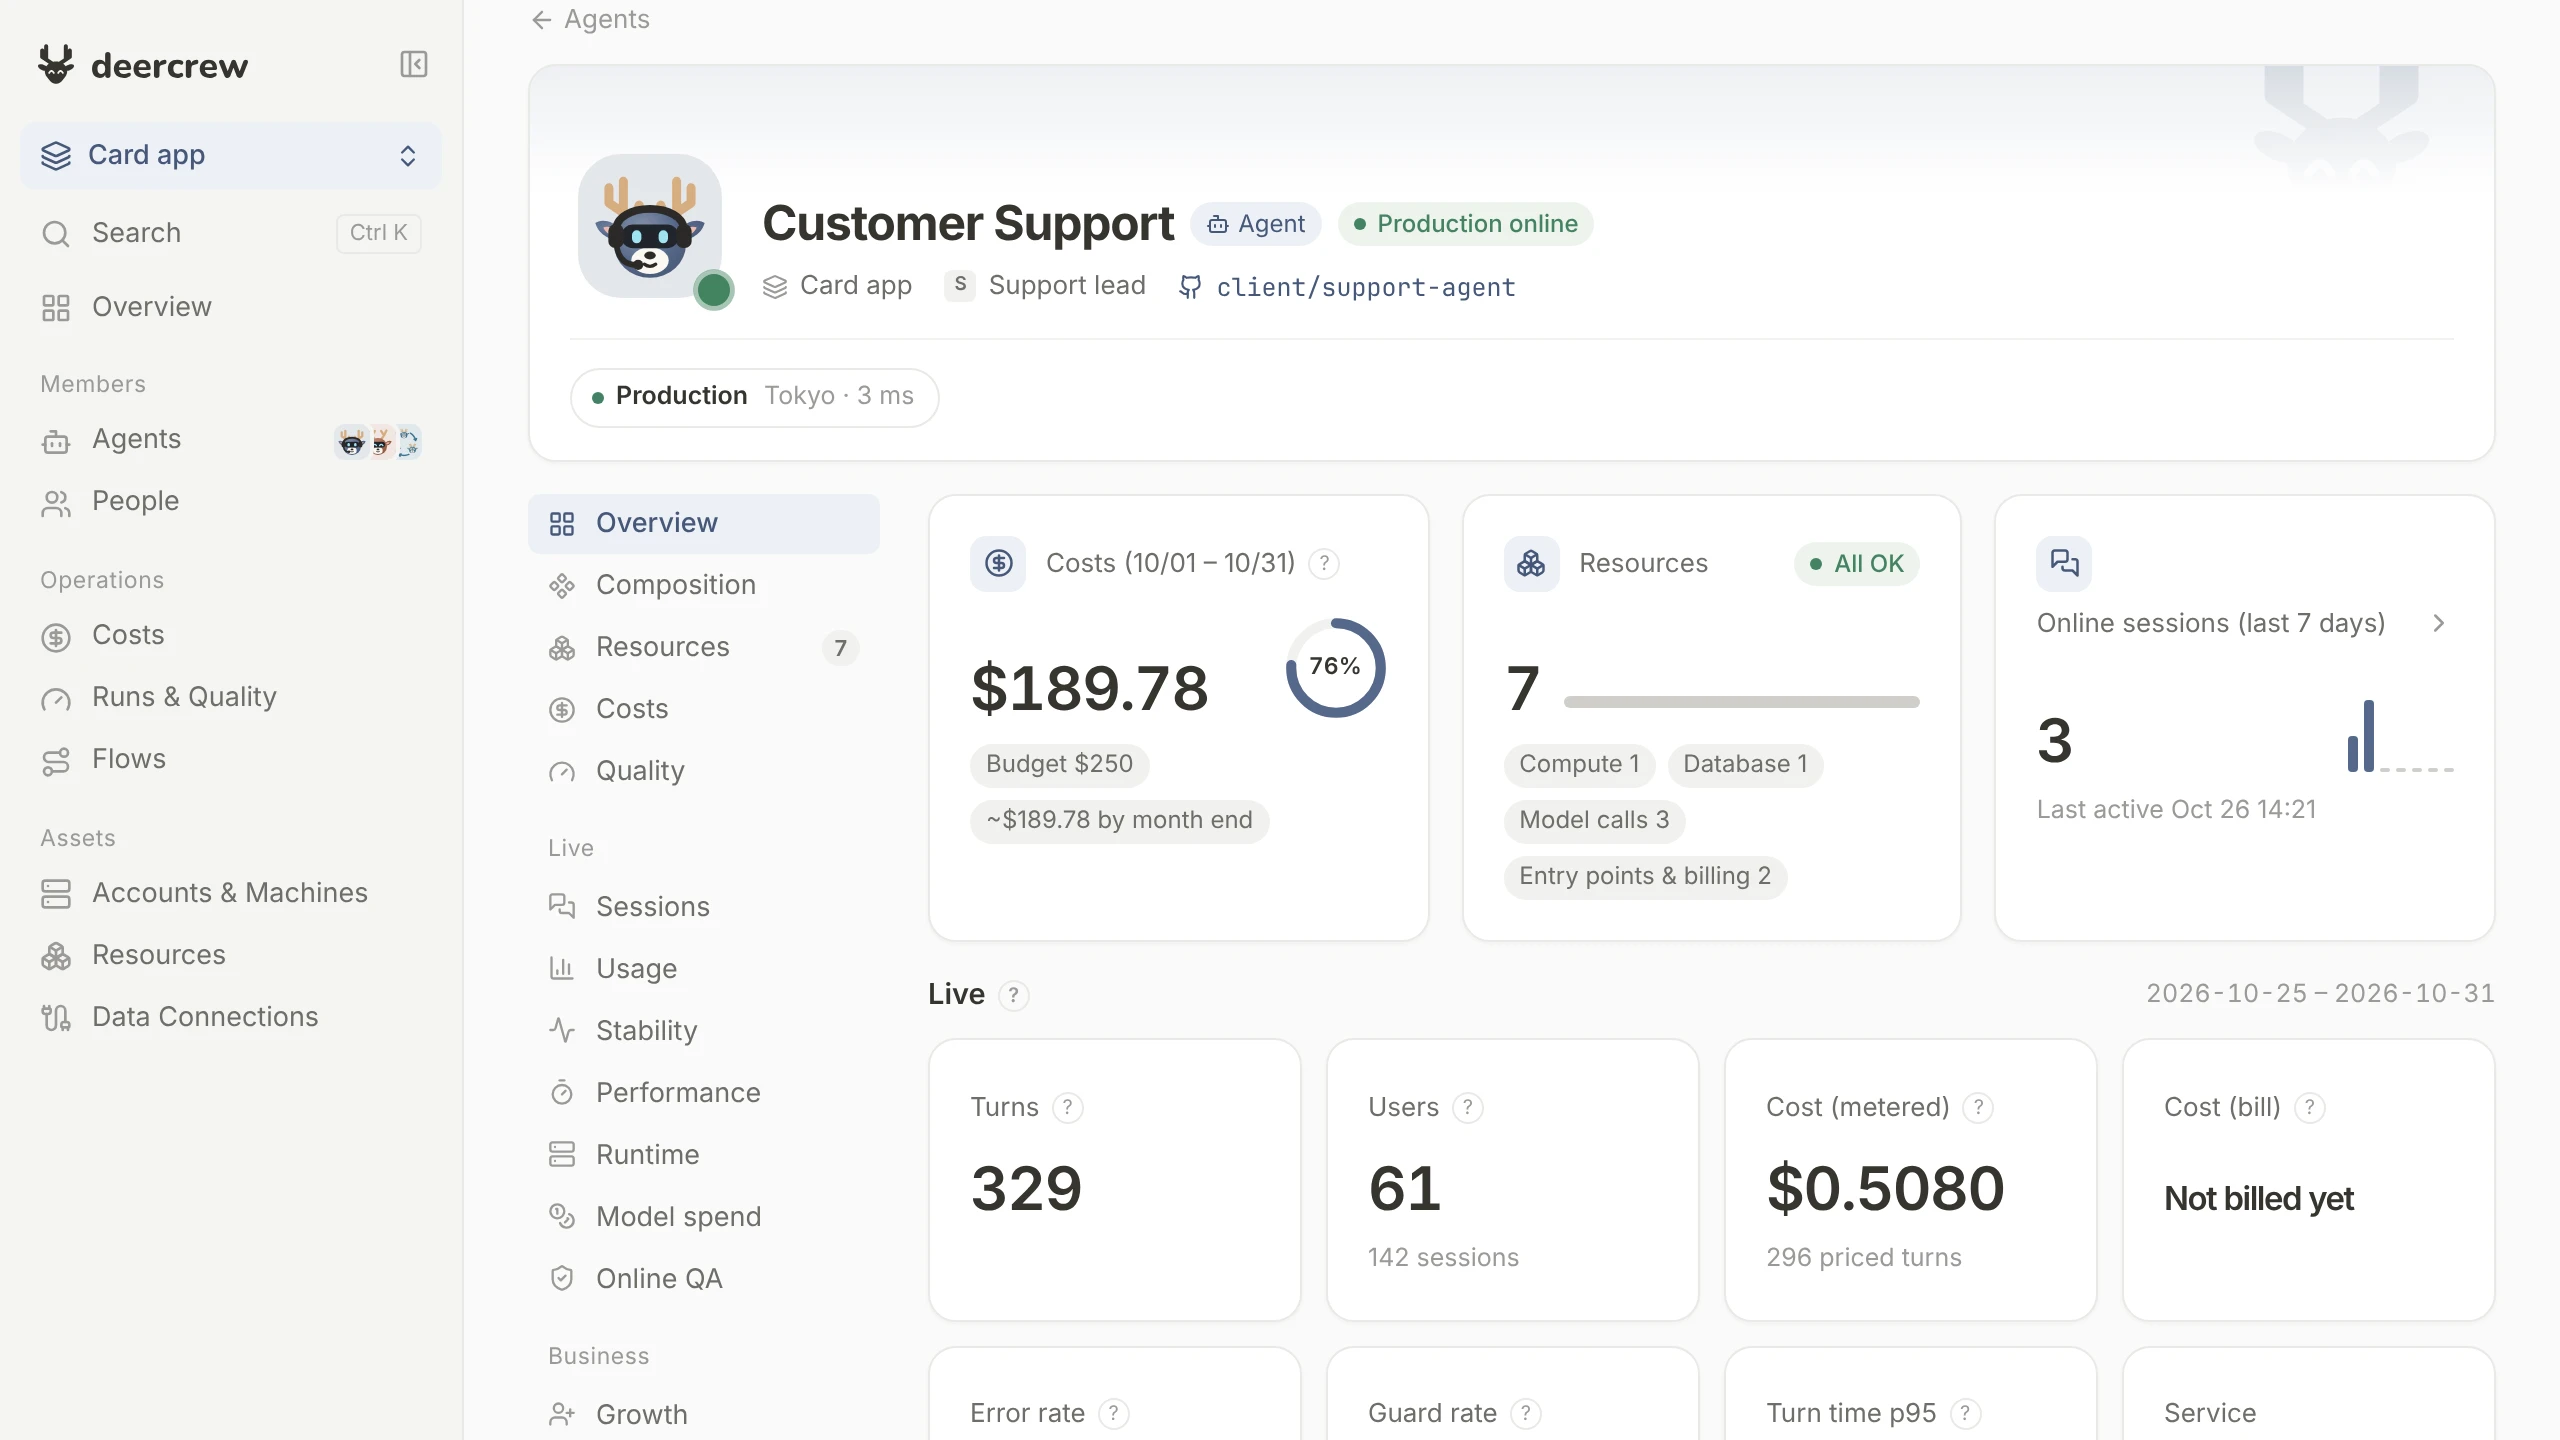
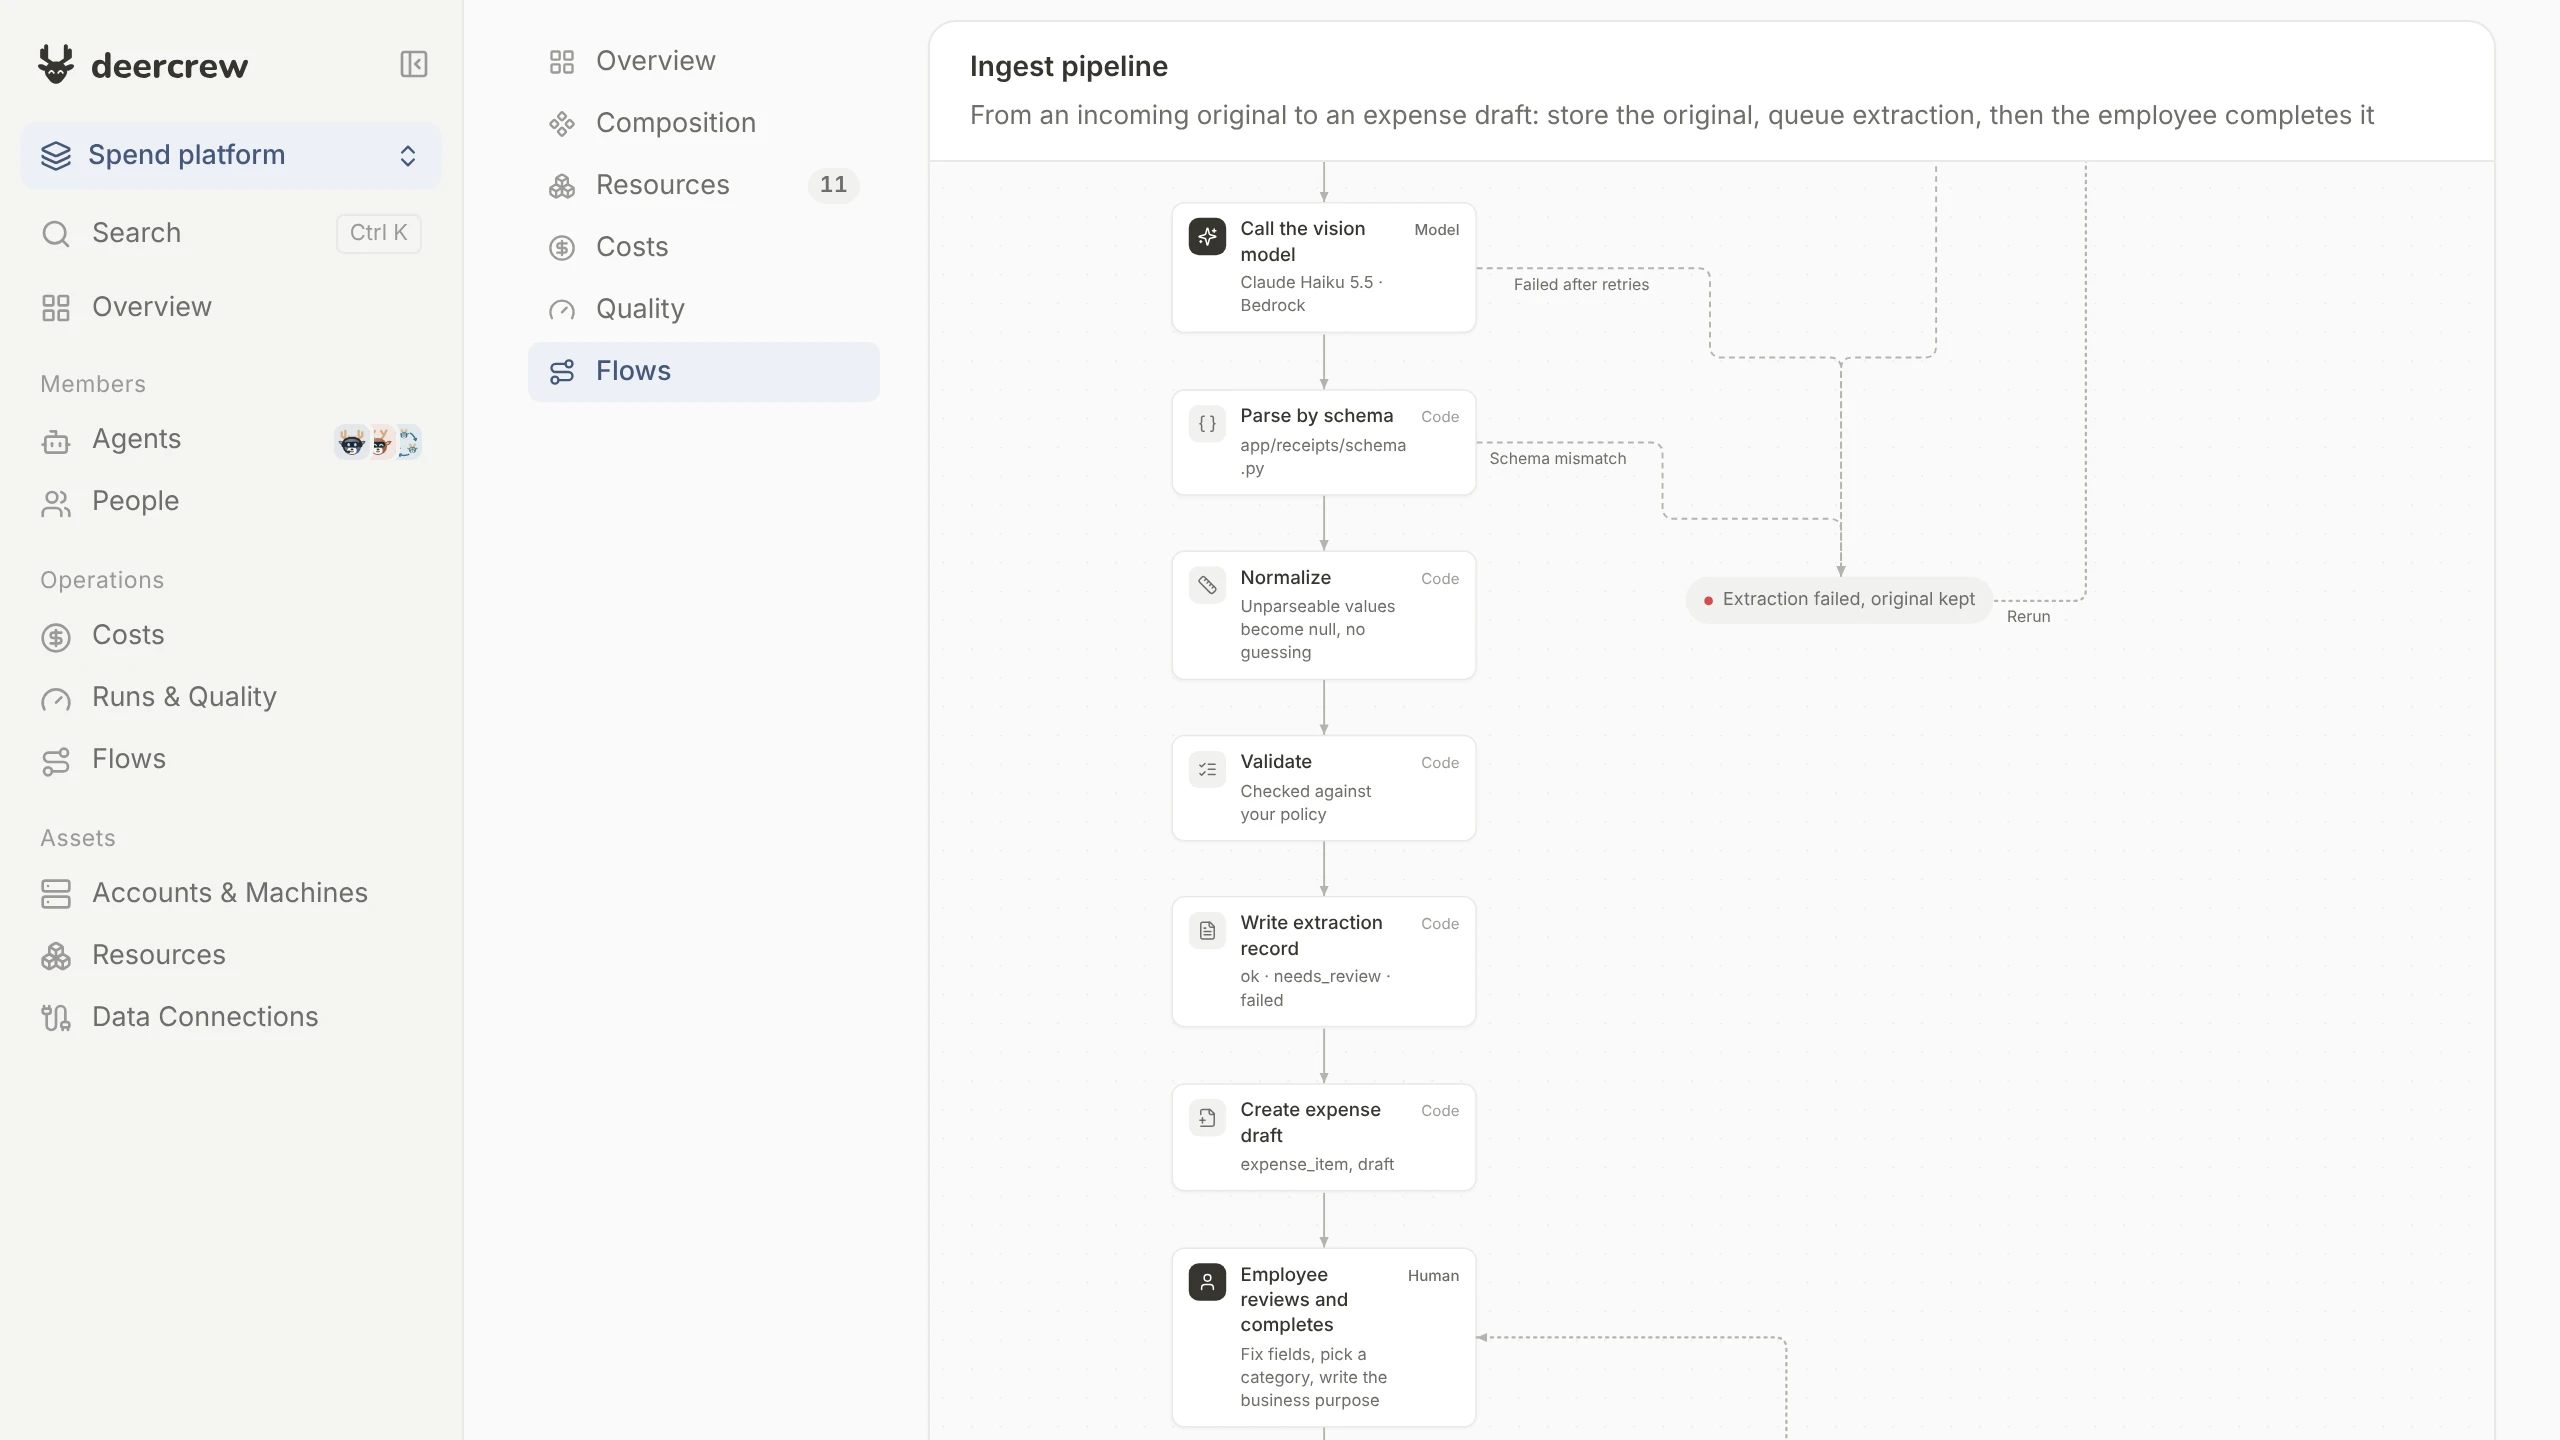
{{ g2cap }}
Every role at a glance
Status, test and live environments, and spend against budget.
Every result on record
Conversations with the checks on each answer, and every eval run before a release.
What it costs
Per role and per environment, by day and by month.
How we start
No long project. One role first, then the next.
- 1
A 30-minute call
We look at your work together and pick the first role.
- 2
Plan, build, evaluate
You get the one-page design. We build on our product and run the evals.
- 3
Live, and looked after
We keep watching and improving it. Want a change? Tell us.
- AWS
- Amazon Bedrock
- LangChainLangGraph
- PostgreSQL
- Cloudflare
Tell us where your team’s time goes.
We’ll reply within one business day. Or write to hello@deercrew.ai.
Book a 30-min call